One Model, Many Graphs: Learning over Attributed Graphs across Heterogeneous Modalities with Vision-Language Models
Jiayi Yang*, Yifang Chen*, Yuanfu Sun, Jiajin Liu, and Qiaoyu Tan
In Proceedings of the 2026 Conference on Empirical Methods in Natural Language Processing, 2026
A single vision-language model, equipped with structure-aware graph adapters, that learns over text-, image-, and multimodal-attributed graphs and generalizes to unseen graphs and modality schemas.
Vision-language models (VLMs) provide a unified representation space for textual and visual information, yet their potential as general-purpose backbones for graph-structured data remains largely unexplored. In practice, attributed graphs exhibit substantial modality heterogeneity: some graphs contain only textual node attributes, others only visual attributes, while still others provide both. Existing graph learning approaches are typically designed for fixed modality schemas, requiring separate models for different settings. We present OMG-VLM (One Model, Many Graphs with Vision-Language Models), a unified framework that leverages a pretrained VLM as a shared backbone and introduces structure-aware graph adapters that integrate neighborhood information while remaining compatible with the VLM’s native embedding space. Extensive experiments across diverse domains show that OMG-VLM consistently outperforms state-of-the-art GNN- and LLM-based baselines on node classification and link prediction, while generalizing well to unseen graphs and varying modality schemas.
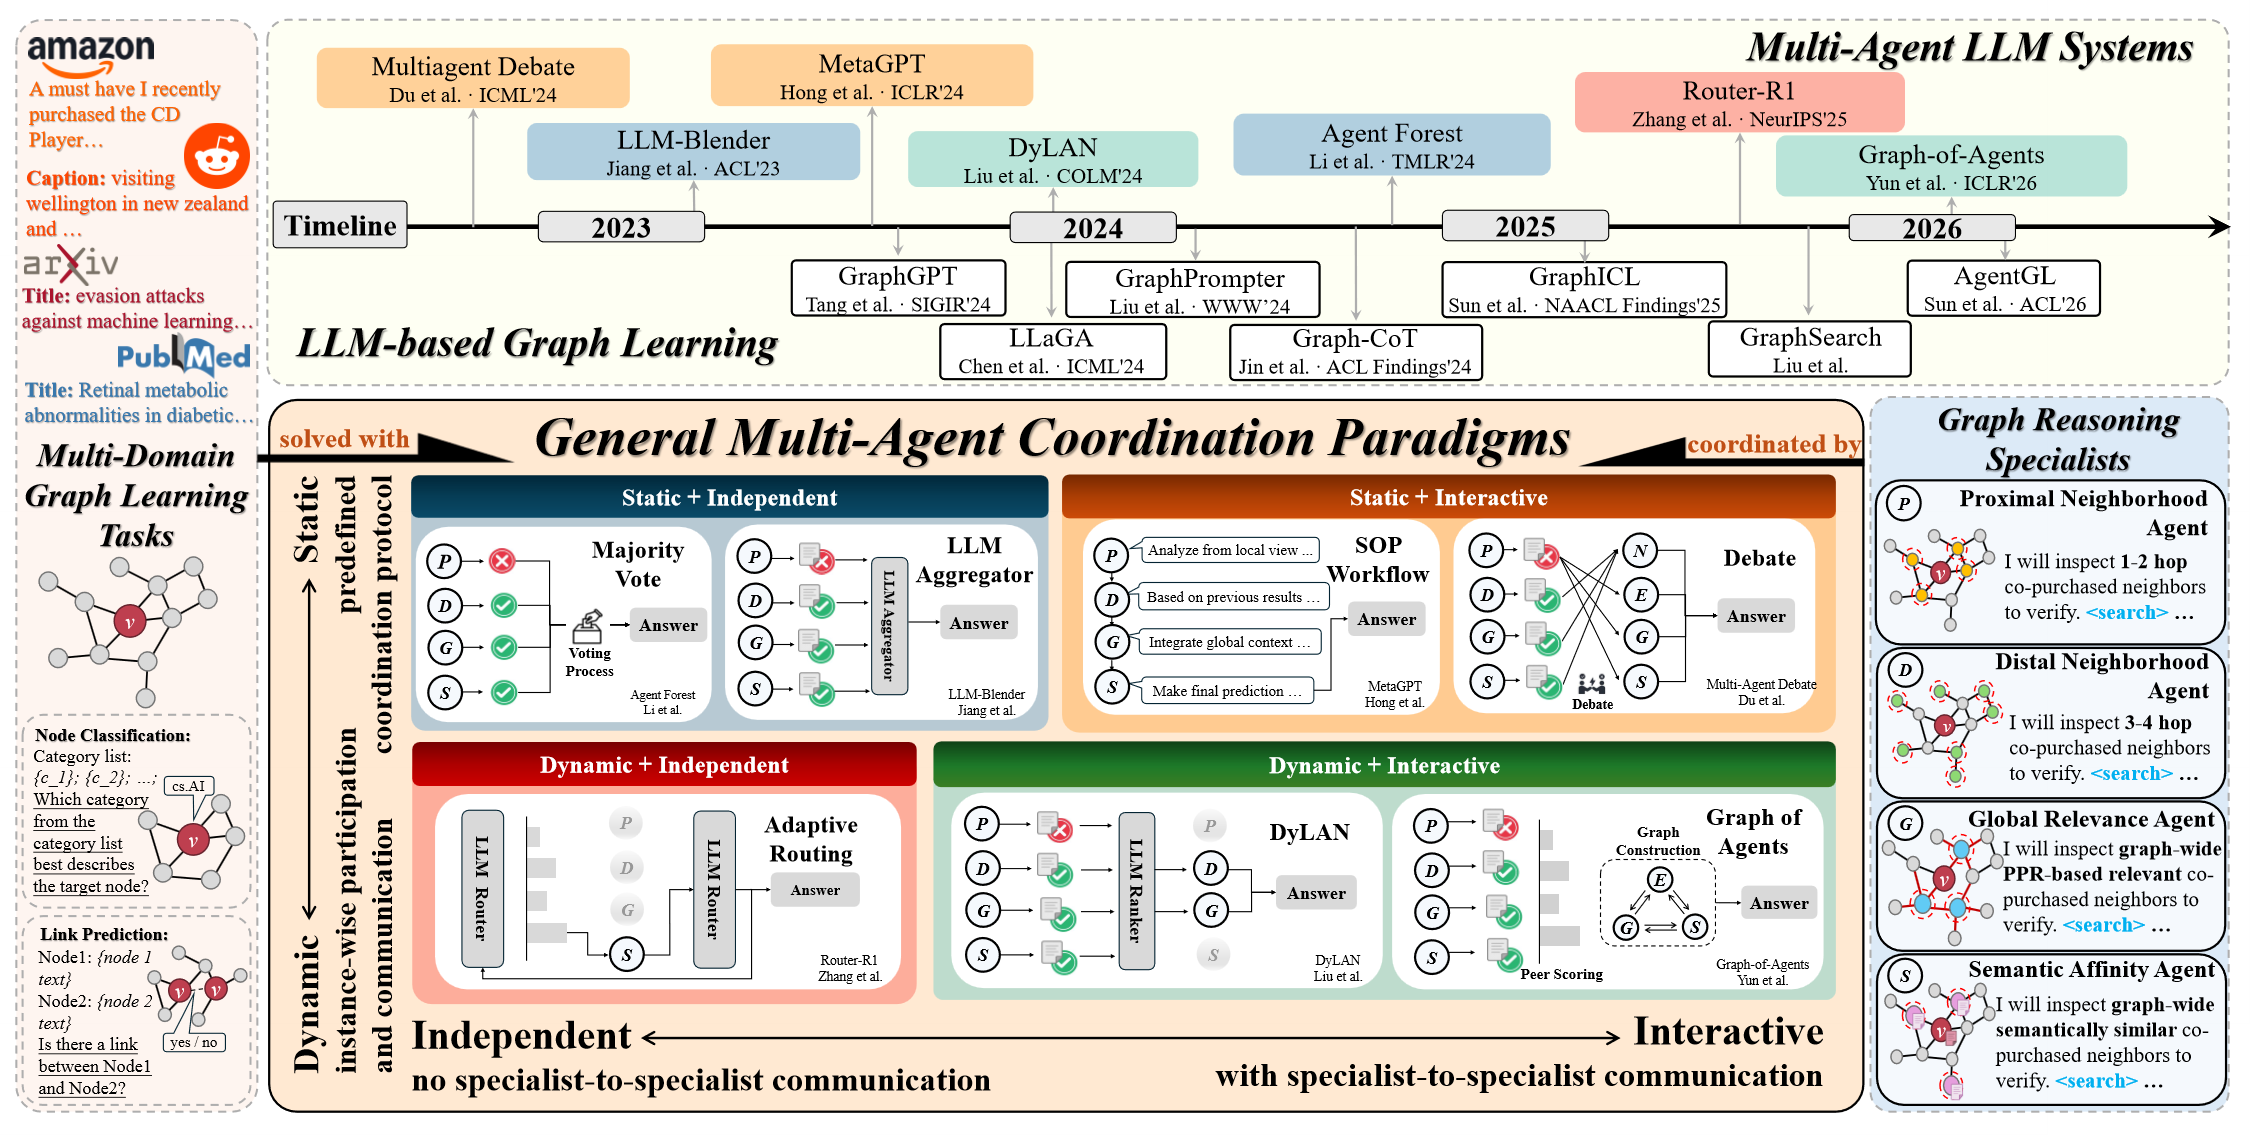 GraphMAS: A Systematic Benchmark of Multi-Agent Coordination for Graph LearningSep 2026A benchmark of LLM-based multi-agent coordination for graph learning, showing that coordinating specialized graph-reasoning agents beats single-agent reasoning and that instance-adaptive specialist selection gives the best accuracy-efficiency trade-off.
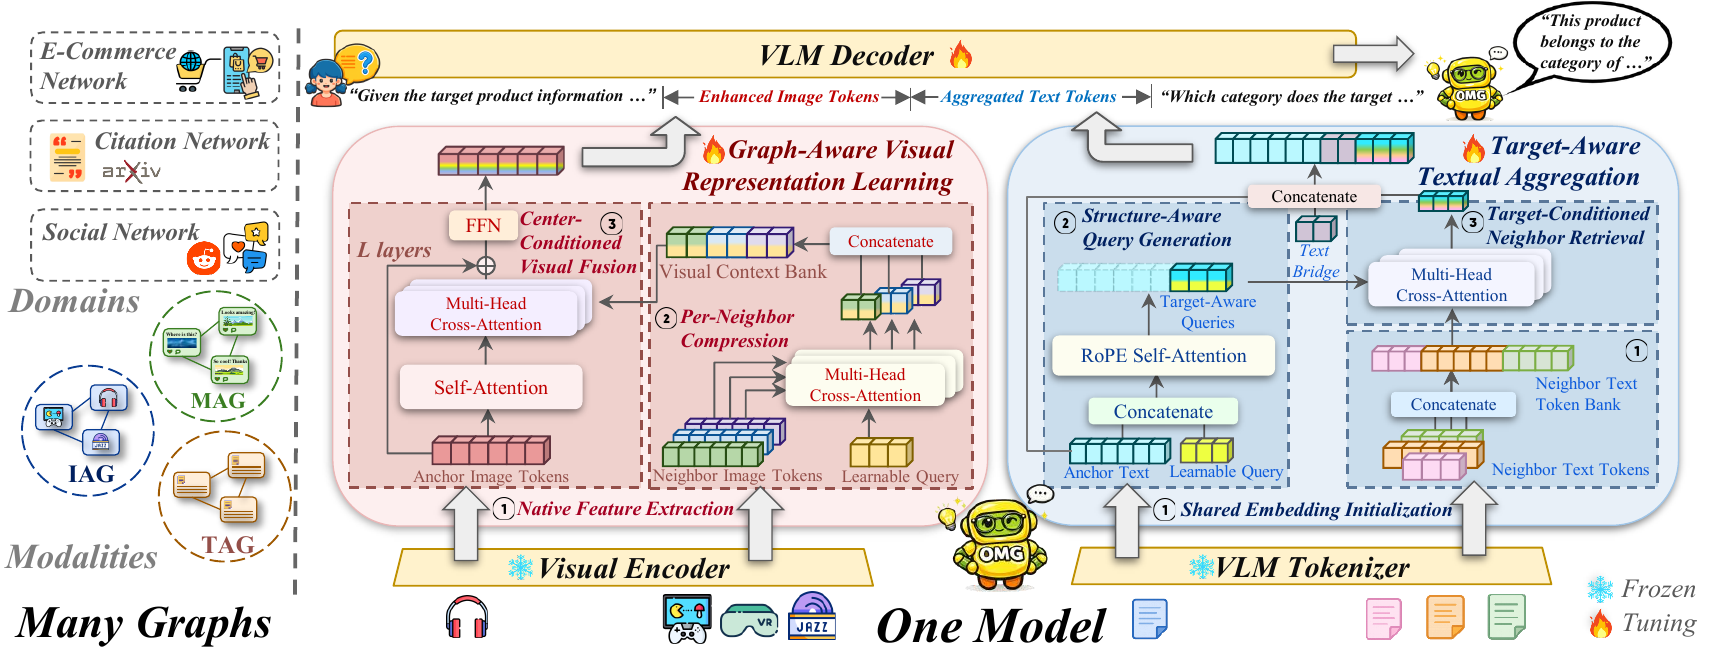 One Model, Many Graphs: Learning over Attributed Graphs across Heterogeneous Modalities with Vision-Language ModelsIn Proceedings of the 2026 Conference on Empirical Methods in Natural Language Processing, 2026A single vision-language model, equipped with structure-aware graph adapters, that learns over text-, image-, and multimodal-attributed graphs and generalizes to unseen graphs and modality schemas.